Solutions architect · Denver, CO

MattySerapio

I'm a solutions architect in Denver with a background in FinOps, analytics engineering, business intelligence, and growth strategy. I build data products and advise some of the largest companies on strategic decisions using their data. Today I'm at Databricks, and before that I spent five years at AWS.

Matty Serapio outdoors with his Shiba Inu
ExpertFinOpsCost allocation, chargeback, and optimization at hyperscale
ExpertDatabricksLakehouse architecture, migrations, Delta Lake and Iceberg. Certified Data Engineer Professional and Generative AI Engineer
DataAnalytics engineering and BIPipelines, data models, and dashboards that leaders use to make decisions
BusinessGrowth strategyBusiness cases and value framing that helped grow some of the largest accounts
Headshot of Matty Serapio
Denver, Colorado

About

I started my career at ConocoPhillips right out of CU Boulder, building the financial models for moving part of the company's on-premises computing to AWS. It showed me how much money sits inside infrastructure decisions, and that has stuck with me ever since.

At Liberty Energy I led a small data team doing what I'd now call analytics engineering. We turned raw completion and production data into clean, trusted datasets and dashboards, and contributed to the data layer behind FracTrends, a tool that lets engineers and customers compare more than 60,000 wells by completion design and production. I owned the data from ingestion all the way to the people making decisions with it.

In 2020 I moved to AWS and spent five years helping some of the largest cloud customers understand their cost and usage data. Along the way I finished my master's in computer science at Penn and helped build an internal tool that about 1,500 people used to find savings.

Today I'm at Databricks, working with large customers on data engineering and analytics migrations across formats like Delta Lake and Iceberg. It's the same thread that has run through my whole career: build good data platforms, and make sure they're worth what they cost.
Where I've worked
Databricks Amazon Web Services Liberty Energy ConocoPhillips

Work

A few projects from the last several years. Customer names are left out.

Demo
Example FinOps analysis
built on synthetic data
Featured project · Interactive dashboard

AMD and Graviton adoption, by business unit

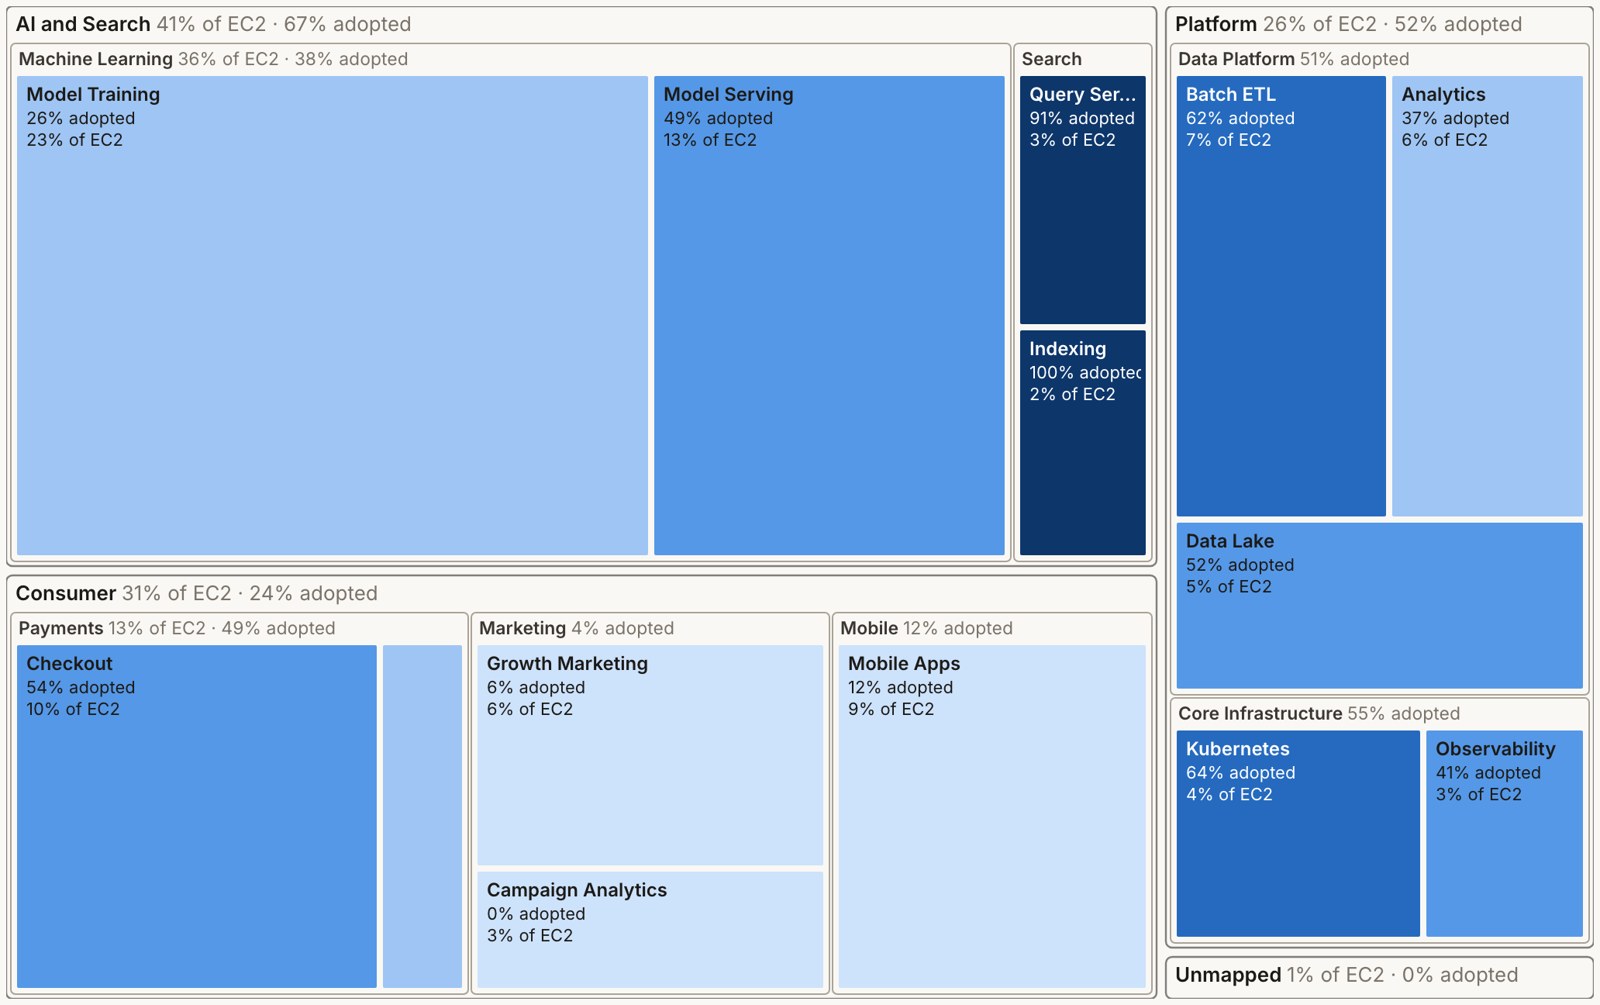
The analysis I ran with large AWS customers, rebuilt end to end on a synthetic Cost and Usage Report. SQL models turn raw billing rows into a three-level business unit view, shared costs are reallocated, and data tests check every dollar. Each team is sized by its share of EC2 spend and shaded by how much of it already runs on AMD or Graviton.

Nested treemap of EC2 spend by level 1, 2, and 3 business units, shaded by AMD and Graviton adoption ● Interactive Explore the dashboard →
SQL · DuckDB · dbt-style models · data tests · D3
60,000+
wells in one self-service tool
Liberty Energy · Analytics engineering

FracTrends well analytics

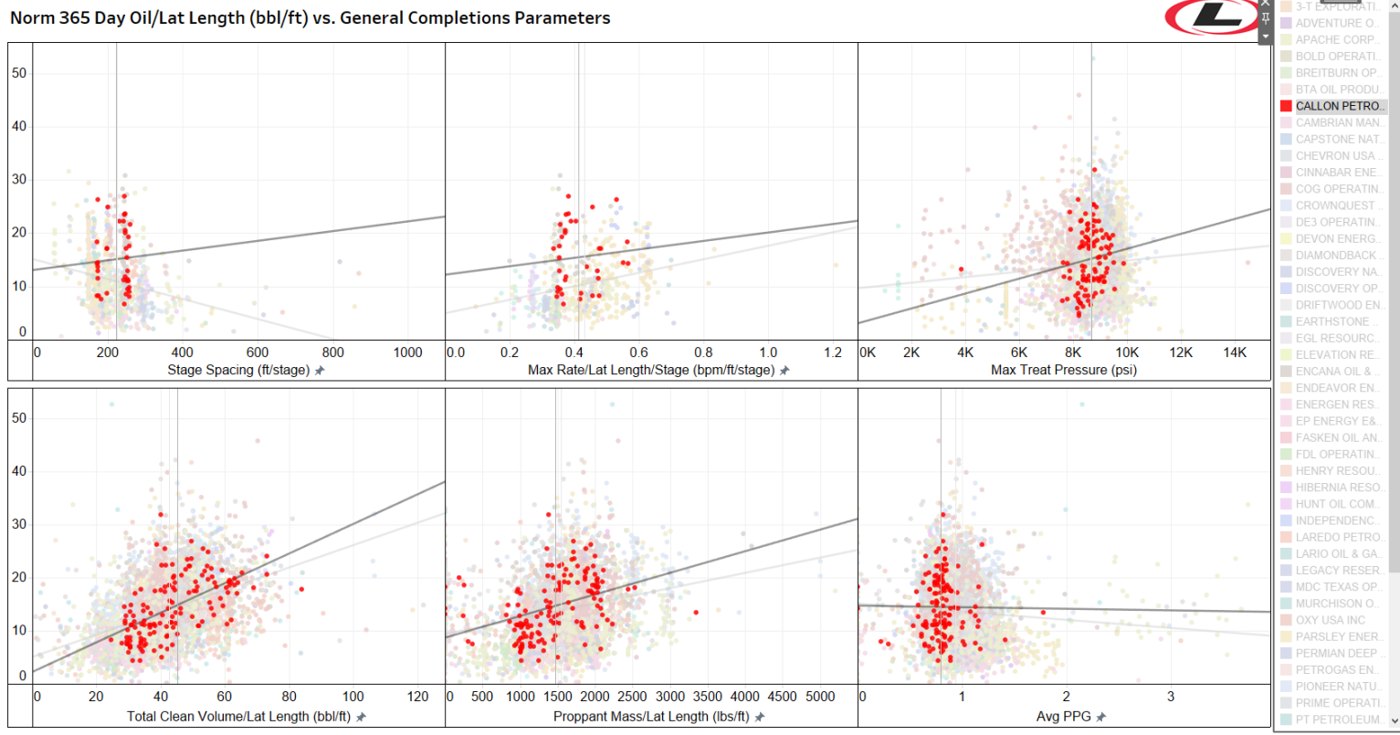
Contributed to the data and semantic layer behind FracTrends, which gives engineers and customers hundreds of views on public completion, petrophysical, and production data. It helps answer who makes better wells and whether that comes from completion design or good rock, and it updates daily.

FracTrends dashboard comparing production against completion parameters across operators
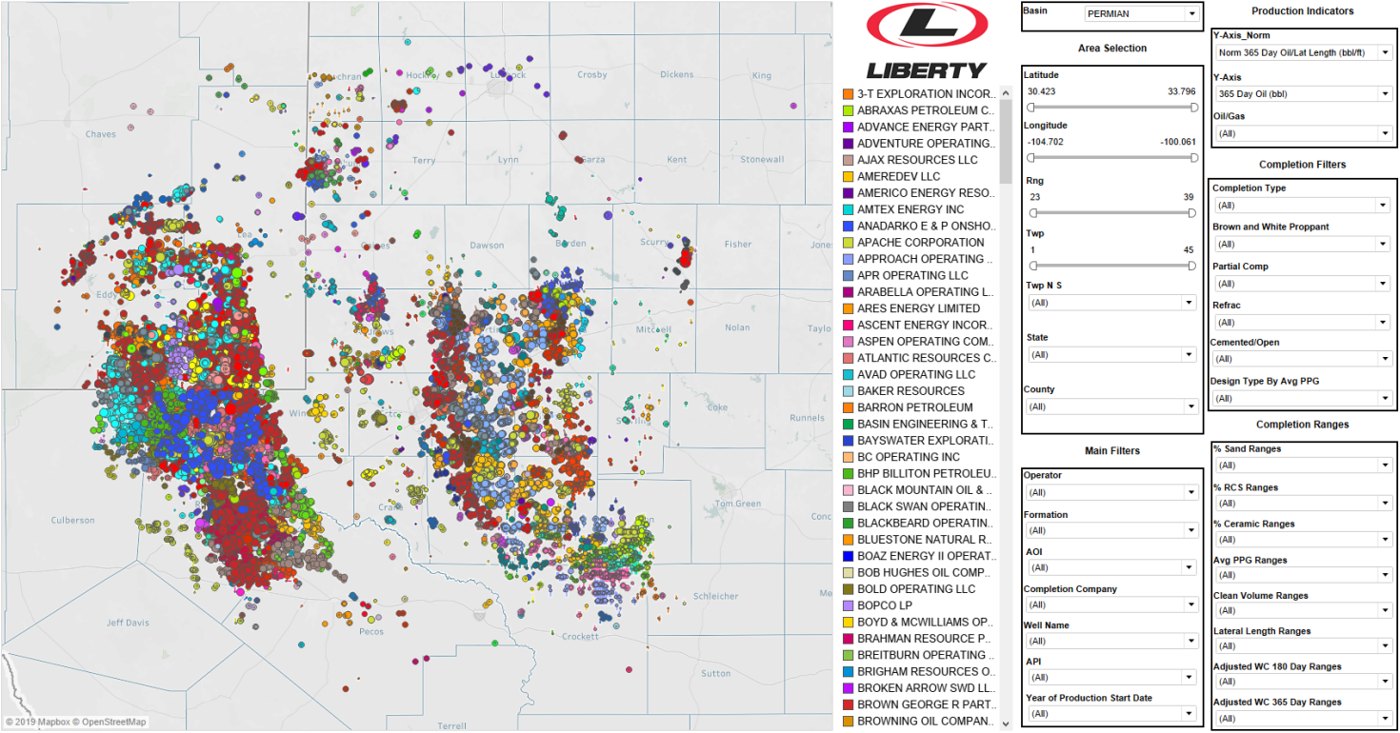
Completion parameters vs. production, highlighted by operator. From Liberty's public FracTrends overview. View the PDF
SQL · ETL · data modeling · PostgreSQL · dashboards
1,500
global users
AWS · Self-service data product

Self-service cost optimization tool

Co-built an internal Python and Streamlit app that helped 1,500 people find cloud savings that used to require a specialist. Its chat interface fanned each question out to multiple LLMs at once, an early version of the multi-agent pattern that's common today, and we tracked adoption across teams.

Python · Streamlit · multi-model LLM · AWS
Delta +
Iceberg
open table formats
Databricks · Advisory

Data format and platform strategy

Advise large customers on choosing and combining open table formats like Delta Lake and Iceberg, and on how to implement Databricks for their workloads, using benchmarks and cost data to guide the decision.

Delta Lake · Apache Iceberg · Spark SQL · benchmarking
$40MM
annual infrastructure savings
AWS · Capacity and utilization

Utilization metrics at AWS

Defined utilization metrics across 70 enterprise accounts and tracked identified versus actioned savings each month. The data guided Graviton and AMD migrations worth $40MM a year.

metrics · capacity · GPU · Graviton
$/query
chargeback dataset
Databricks · Data modeling

Cost per query attribution

Modeled cost per query from Redshift query logs so shared warehouse spend could be charged back to the teams using it.

SQL · data modeling · Redshift

Talks and labs

Videos, a hands-on lab, and a product overview from my work at AWS and Liberty Energy.

FracTrends map of horizontal wells in the Permian Basin with operator and completion filters
Liberty Energy · Product overview

FracTrends Viewer

Liberty's public overview of the well analytics tool my team contributed data to: a map and hundreds of plots across 60,000+ horizontal wells, with filters by operator, formation, and completion design. Open the PDF

Amazon Web Services

Compute proportional cost reallocation using SQL

Splitting shared compute cost across teams based on how much each one uses. Watch on YouTube

Amazon Web Services

Compute proportional split cost reallocation using SQL

The same approach applied to split cost allocation data for containers. Watch on YouTube

The Keys to AWS Optimization · S7 E12

How to find optimization opportunities in the CUR

Querying the AWS Cost and Usage Report (CUR) to find savings. Watch on YouTube

The Keys to AWS Optimization · S7 E7

Rightsizing: let's make it easy

Using utilization data to right-size compute. Watch on YouTube

The Keys to AWS Optimization · S4 E2

FinOps with financial services

FinOps practices for financial services companies. Watch on YouTube

Skills

Data engineering

  • SQL: Presto, Trino, Spark SQL, Databricks SQL
  • Python
  • Apache Spark
  • Airflow
  • Delta Lake and Iceberg
  • Kafka

Analytics

  • Data modeling
  • Metrics design
  • Tableau and Looker
  • Power BI
  • Databricks AI/BI
  • Streamlit

Cloud and FinOps

  • AWS and Databricks
  • Cost allocation and chargeback
  • Capacity and utilization
  • Kubernetes
  • Terraform

ML and AI

  • Generative AI (Databricks certified)
  • MLflow
  • scikit-learn
  • LLM applications
  • Claude Code and Cursor

Certifications: Databricks Data Engineer Professional, Data Engineer Associate, Data Analyst Associate, Machine Learning Associate, and Generative AI Engineer Associate. AWS Certified Cloud Practitioner.

Experience

2025 – Present

Delivery Solutions Architect

Databricks · Strategic Accounts

Technical lead for Databricks implementations at strategic accounts. I help customers design their data platforms, migrate workloads, and get the most out of Databricks, and I bring their feedback to our product teams.

2020 – 2025

Senior Optimization Solutions Architect

Amazon Web Services · Strategic Accounts

Helped enterprise customers analyze cloud cost and usage data and run more efficiently. Built internal tools and training for AWS teams, and gave feedback that shaped AWS cost management features.

2018 – 2020

Engineering Data Team Lead, Data Engineering and Analytics Engineering

Liberty Energy

Led a team of data specialists doing analytics engineering: pipelines, data models, and dashboards for engineering and operations, including contributing to the FracTrends well analytics tool.

2014 – 2017

Infrastructure Performance Analyst (FinOps)

ConocoPhillips

Analyzed infrastructure performance and cost, and built cost models for moving on-premises workloads to the cloud.

University of PennsylvaniaMaster of Computer Science
University of Colorado BoulderBS, Business Administration

Contact

LinkedIn is the best way to reach me.